Preprint · 2025
Perception & Localization in Unstructured EnvironmentsTemporally Consistent Unsupervised Segmentation for Mobile Robot Perception
Christian Ellis, Maggie Wigness, Craig Lennon, Lance Fiondella
arXiv preprint arXiv:2507.22194, 2025
Abstract
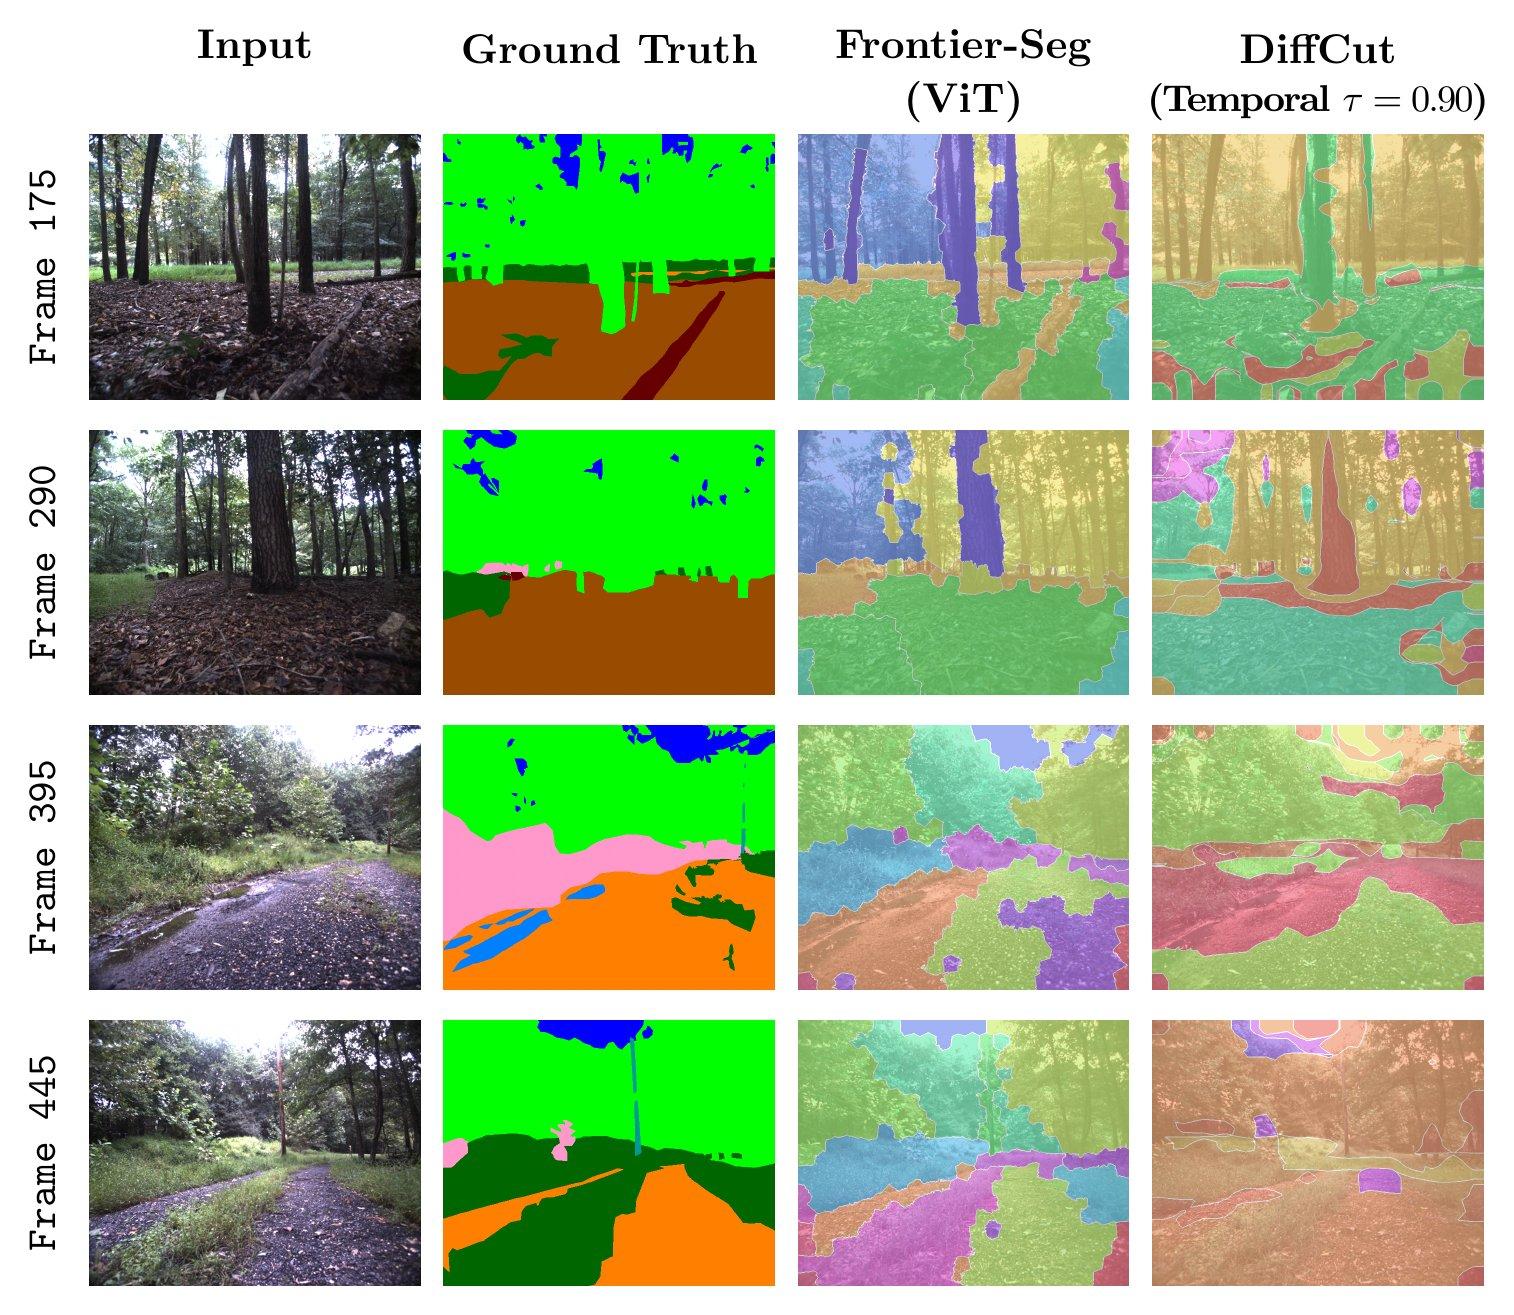
Rapid progress in terrain-aware autonomous ground navigation has been driven by advances in supervised semantic segmentation. However, these methods rely on costly data collection and labor-intensive ground truth labeling to train deep models. Furthermore, autonomous systems are increasingly deployed in unrehearsed, unstructured environments where no labeled data exists and semantic categories may be ambiguous or domain-specific. Recent zero-shot approaches to unsupervised segmentation have shown promise in such settings but typically operate on individual frames, lacking temporal consistency-a critical property for robust perception in unstructured environments. To address this gap we introduce Frontier-Seg, a method for temporally consistent unsupervised segmentation of terrain from mobile robot video streams. Frontier-Seg clusters superpixel-level features extracted from foundation model backbones-specifically DINOv2-and enforces temporal consistency across frames to identify persistent terrain boundaries or frontiers without human supervision. We evaluate Frontier-Seg on a diverse set of benchmark datasets-including RUGD and RELLIS-3D-demonstrating its ability to perform unsupervised segmentation across unstructured off-road environments.
Cite
@misc{ellis2025temporally,
  title = {{Temporally Consistent Unsupervised Segmentation for Mobile Robot Perception}},
  author = {Christian Ellis and Maggie Wigness and Craig Lennon and Lance Fiondella},
  year = {2025},
  eprint = {2507.22194},
  archivePrefix = {arXiv}
}